Why observability became a strategic priority
Modern distributed systems differ fundamentally from legacy monolithic architectures. Today software requires DevOps teams to monitor their systems effectively and improve them continuously to minimise disruptive events, all the more so as deployment frequency has exploded with continuous integration and delivery.
Two capabilities become central: making the system observable, to understand what is actually happening, and making it resilient, so it absorbs incidents without collapsing. A system can be monitored without being observable, receiving alerts says nothing about the cause of an unforeseen problem. It is this interplay between observability and resilience that we explore here, along with the practices and tooling that, in 2026, make it possible to implement at scale.
From distributed systems to microservices architectures
From the monolith to the service mesh
Traditional monolithic systems operated within tightly layered structures, managed by in-house IT teams at specific locations. Contemporary distributed systems, by contrast, consist of multiple interconnected components spread across several environments and platforms: containers orchestrated by Kubernetes, serverless functions, managed databases, message queues and third-party APIs all coexist within a single processing chain.
A distributed system can be defined as a network of interconnected components functioning together as a single state. This approach lets companies incorporate diverse technologies while preserving scalability and resilience, but its complexity demands standardised interface contracts across components to ensure availability, compatibility and data consistency.
The cost of distribution: complexity that relocates, not disappears
More and more organisations are replacing monolithic designs with microservices architectures. Each service operates independently within a cloud environment while remaining connected to operational systems, enabling deployment and scaling service by service, in step with business needs.
This gain in agility has a cost: complexity does not disappear, it moves from the code to the network. A request that used to travel through a handful of function calls within a single process now travels through ten, twenty, sometimes fifty services, each with its own latency, its own dependencies and its own failure modes. It appears in e-commerce, banking and manufacturing alike, sectors where availability and the ability to scale are paramount.
The three pillars of observability
Logs, metrics and traces: complementary signals
Observability refers to the ability to understand a system internal state purely from the data it exposes outward, without having to modify it for every new question one might ask. It rests on three categories of signals that complement rather than replace one another: structured logs, which capture discrete events with their context; metrics, which aggregate numerical measurements over time to detect trends; and distributed traces, which reconstruct the full path of a request across the services it traverses.
From reactive monitoring to exploratory investigation
Managing a distributed system effectively means making it observable in the fullest sense: being able to isolate a specific request and identify the component responsible for an anomaly, including for questions that were not anticipated at instrumentation time. That is the difference between classic monitoring, which checks hypotheses known in advance through fixed dashboards, and mature observability, which lets teams freely explore high-cardinality data to form new hypotheses in the middle of an incident.
Tooling distributed tracing and signal correlation
OpenTelemetry as a common foundation
Instrumentation has standardised around OpenTelemetry, which unifies the collection of logs, metrics and traces behind a common API and protocol, independent of whichever observability vendor is chosen downstream. Each service propagates a trace identifier and a span identifier across its outgoing calls, making it possible to reconstruct, service by service, the exact path a request follows and isolate the link introducing latency or errors.
Correlating to shorten diagnosis time
Once data is collected, the real challenge is correlation: linking a slow trace to the deployed code version, to the Kubernetes node involved, to the scaling event that preceded the incident. Modern observability platforms automate this correlation and cut average diagnosis time, which directly affects mean time to resolution, one of the metrics most closely watched by SRE teams.
Designing resilience: patterns and anti-patterns
The patterns that absorb failure
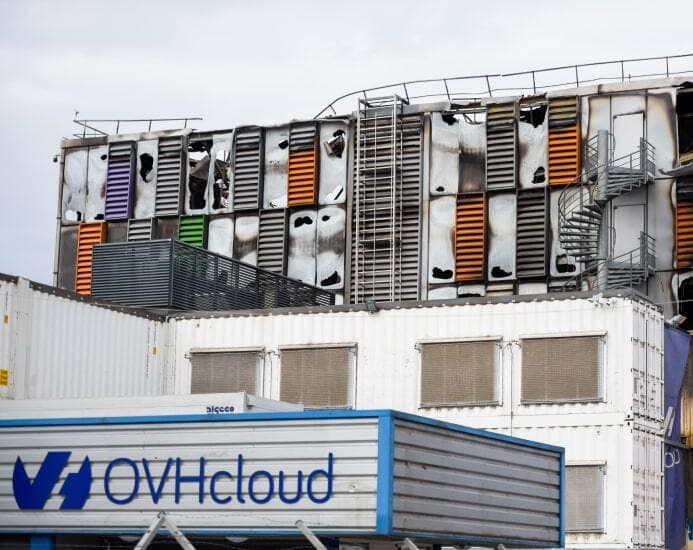
Resilience refers to an application ability to recover its previous operating conditions after an adverse event or failure. It is not just about avoiding outages, but about preparing for and managing those events in order to return to standard protocol afterwards. In practice, it rests on a set of proven patterns: the circuit breaker, which cuts calls to a failing service rather than letting them pile up; retry with exponential backoff and jitter, which avoids synchronised retry storms; the bulkhead, which isolates resource pools so a local saturation does not contaminate the rest of the system; and the timeout, too often neglected, which bounds how long a call waits on a remote dependency.
Validating resilience through experimentation
These patterns are not enough if they are never tested under real conditions. Chaos engineering, the controlled injection of failures in production or pre-production, has become the reference method for verifying that a system behaves as expected when a node goes down, an availability zone becomes unreachable, or an external dependency responds with ten times its usual latency.
Event-driven architecture as a safety net
In a distributed system, resilience is built at the component level, not only at the level of the overall application. Event-driven architecture contributes directly to it: by replacing blocking synchronous calls with message queues and event streams, it provides a form of safety by allowing an individual system to fail without compromising the operation of the whole.
A producer service publishes an event and continues processing without waiting for the consumer to handle it; if that consumer is temporarily unavailable, the message stays in the queue until it can be picked up, without loss or cascading blockage. This temporal decoupling mechanically reduces the blast radius of an isolated failure and makes it easier to absorb load spikes thanks to the natural buffer the queue provides.
Steering with SLIs, SLOs and an SRE culture
Observing a system is not enough to steer its reliability: the collected signals must be translated into measurable objectives shared with the business. Service level indicators (SLIs) measure a concrete dimension of the user experience, latency, error rate, availability, while service level objectives (SLOs) set the acceptable threshold over a given time window, typically around 99.9% for a critical service.
The gap between the objective and actual performance forms the error budget: as long as it is not exhausted, the team can take reasoned risks, deploy more often, experiment with new features. Once it runs out, priority mechanically shifts toward stabilisation. This discipline, driven by SRE teams, replaces the binary chase for zero incidents with a continuous, documented trade-off between velocity and reliability.
Bringing observability and resilience together with Adservio
Bringing observability and resilience together is as much about method as tooling. A complete technical stack, OpenTelemetry, a tracing backend, an alerting engine correlated with SLOs, only creates value when it is backed by clear runbooks, regular chaos engineering exercises and a blameless post-mortem culture that captures learning from every incident.
At Adservio, we support organisations in implementing these practices on their distributed systems, adapting them to the reality of each project, its business criticality and its DevOps maturity, and steering clear of costly pitfalls and anti-patterns, excessive instrumentation that drowns the useful signal, poorly calibrated alerting that burns out on-call teams, or resilience bolted on after the fact rather than built in from the start.
STAY POSTED
Get our next analyses and field notes straight to your inbox.